Data Quality & KPI Automation Pipeline
View on GitHubData Engineering
Data Quality & KPI Automation Pipeline
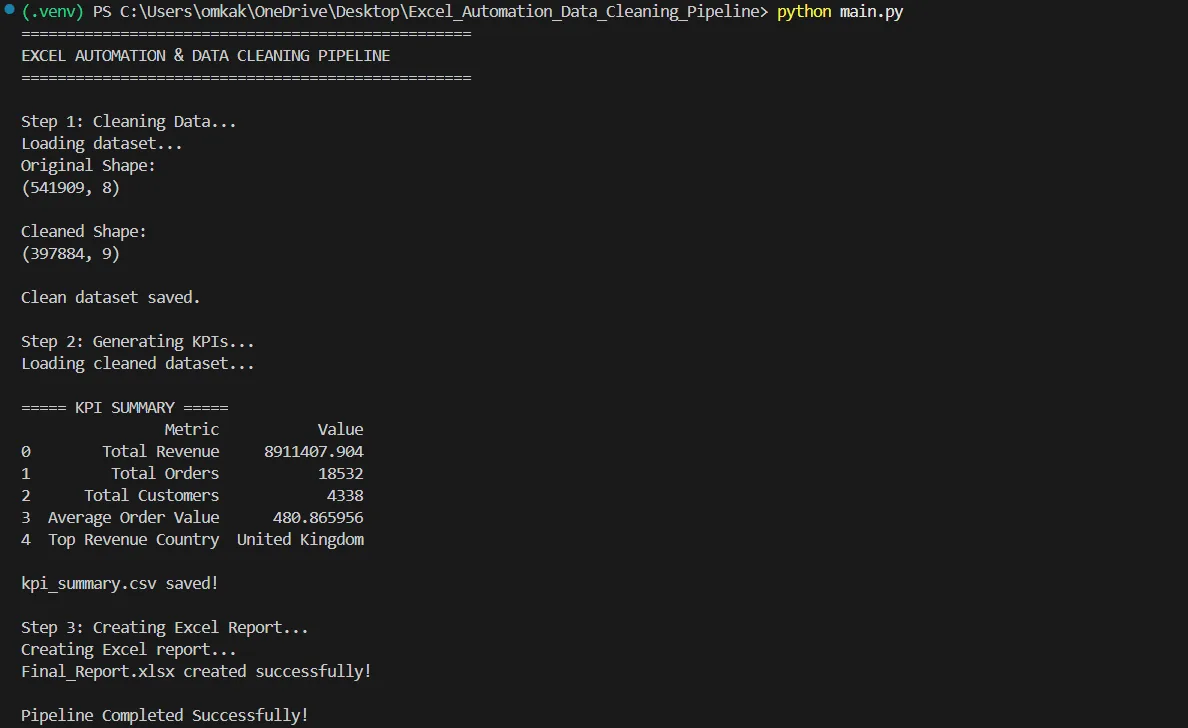
A modular Python pipeline checks 541,909 retail transactions and retains 397,884 valid records for KPI analysis and a formatted Excel report.
PythonPandasOpenPyXLETLAutomation
Key Highlights
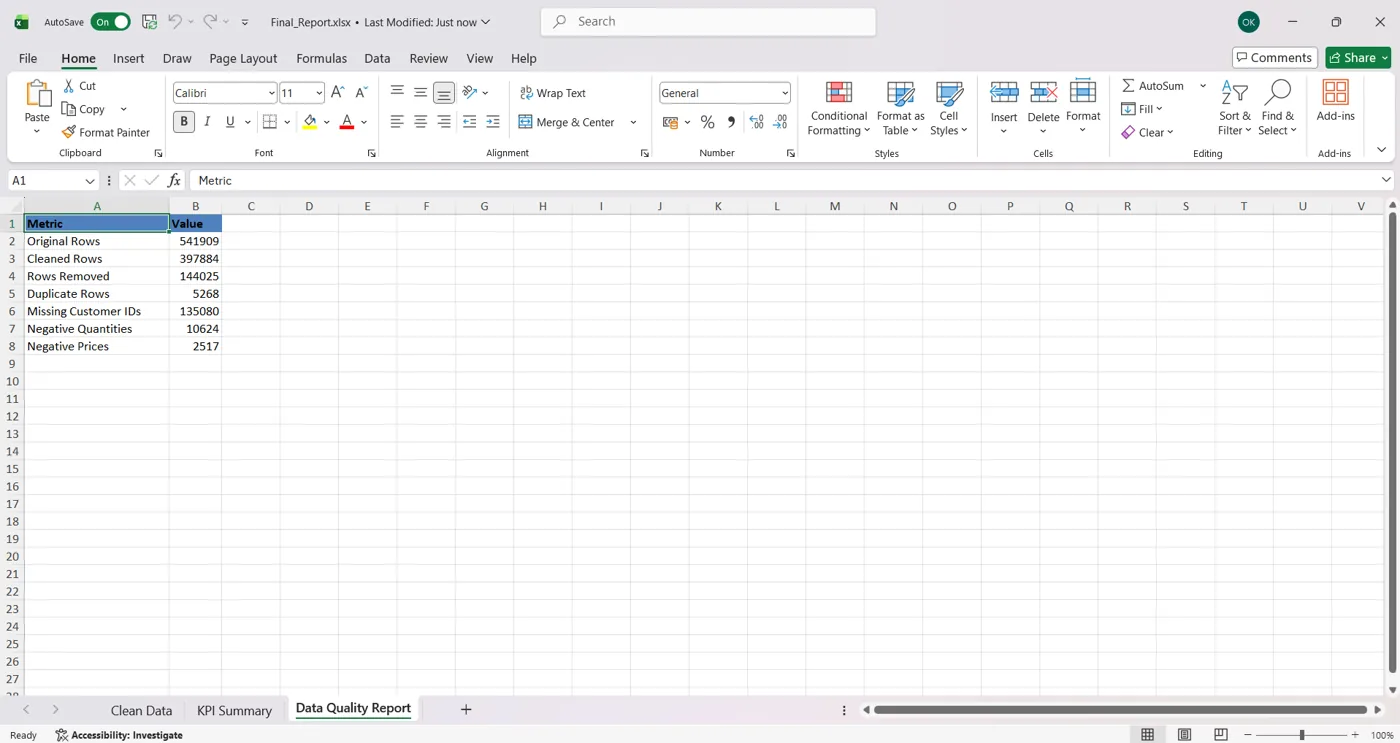
- Detected 5,268 duplicate rows and 135,080 records with missing customer IDs.
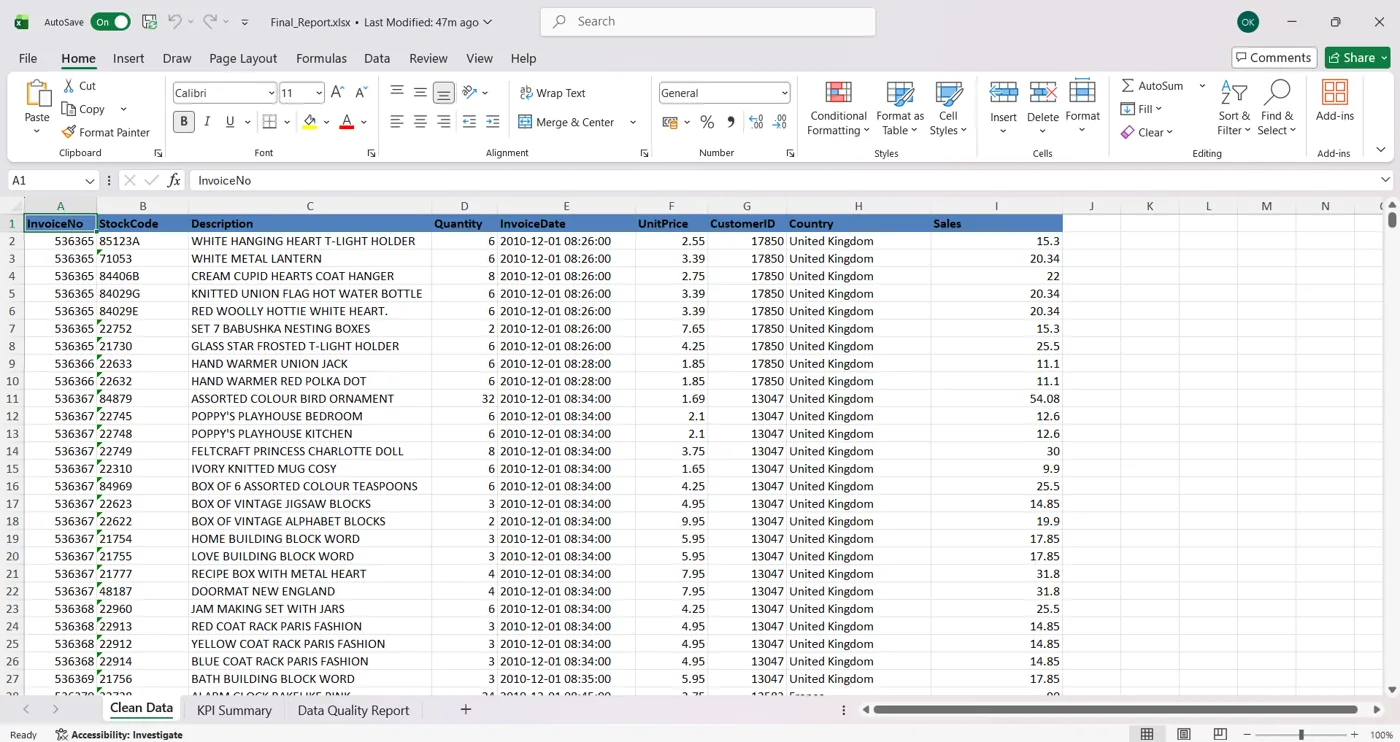
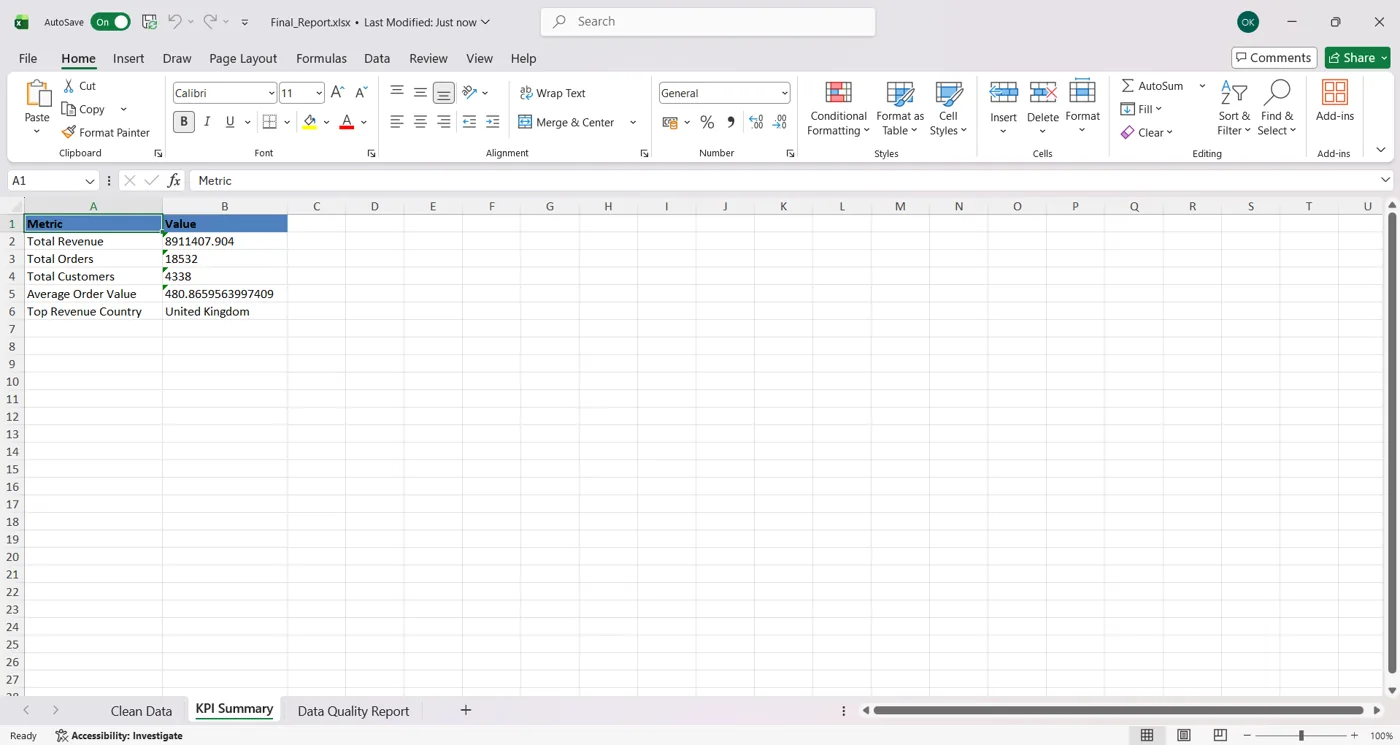
- Computes KPIs and creates a three-sheet Excel report for cleaned data, metrics and data-quality findings.
Tech Stack
PythonPandasOpenPyXLETLAutomation
Overview
An automated cleaning and reporting pipeline for the Online Retail dataset. It applies auditable quality rules before calculating business KPIs and exporting the results.
Methodology
- Validate and clean invoice, customer, quantity and price fields.
- Remove duplicate records and invalid transactions, then calculate sales metrics.
- Write cleaned data, KPI results and quality findings to a formatted workbook.
Results & Findings
- 541,909 source rows; 397,884 retained after cleaning.
- The README reports 5,268 duplicates, 135,080 missing customer IDs, 10,624 nonpositive quantities and 2,517 nonpositive prices.
- Reported KPIs include revenue of 8,911,407.90 and 18,532 orders.
Getting Started
The repository documents Python 3.10 or later and a command-line entry point.
python -m venv .venv
# Activate the environment, then install requirements
pip install -r requirements.txt
python main.py
Project Structure
- main.py: pipeline entry point
- scripts/: cleaning, KPI, quality-audit and Excel-report modules
- reports/: generated workbook outputs
Screenshots